Inside NeedSift’s Ranking Algorithm: The Formula Behind Every Score
The exact NeedSift ranking formula, signal weights, freshness windows, vote safeguards, site-quality checks, and the reasoning behind every product score.
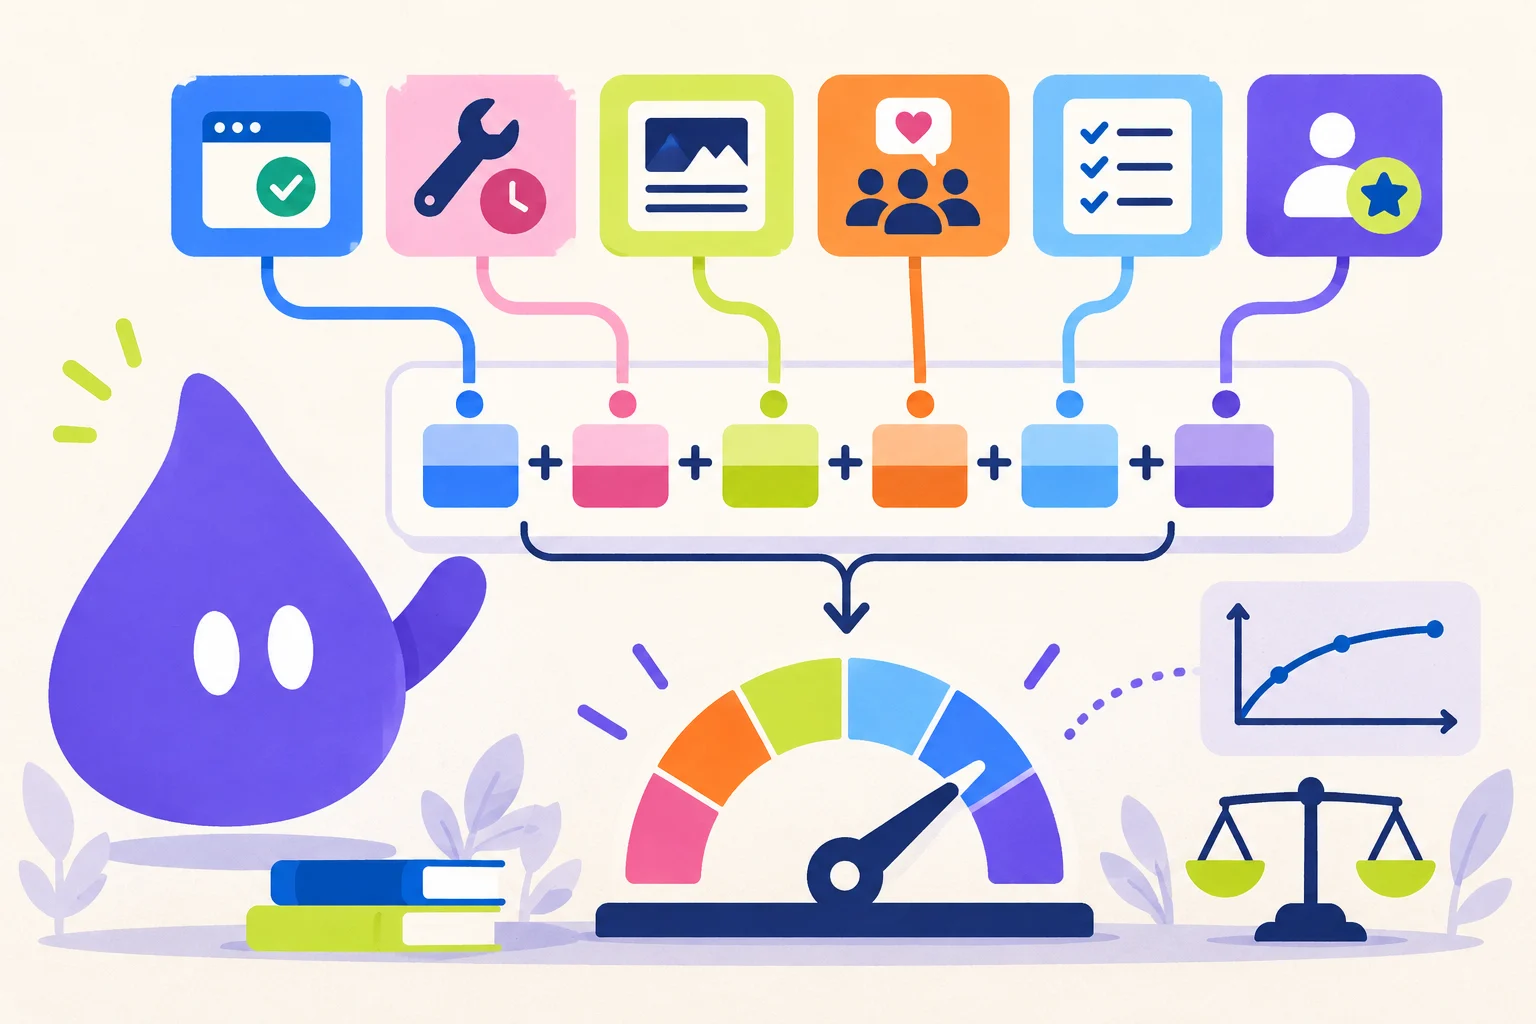
One score, six independent signals
NeedSift’s catalog is not ordered by raw upvotes, page count, or the date a product was submitted. The backend calculates a score from zero to one hundred before returning the catalog. The same stored score is used by every visitor, so cards do not jump into a different order after hydration.
The formula combines reliability, recent maintenance, website quality, public activity, listing completeness, and authenticated community support. A large audience helps only inside the capped community component. A small product can reach the top by staying available, shipping, explaining itself clearly, and maintaining credible public evidence.
This page describes version 2 of the formula, in effect since September 25, 2026. Every change to the algorithm is listed in the version history at the end of the article, so builders can see what moved and why.
Score = min(100, 0.20U + 0.25M + 0.15Q + 0.10S + C + V)U, M, Q, and S are normalized from 0 to 100. C and V contribute directly from 0 to 15 points each. The total is rounded to two decimals and capped at 100.- Uptime U: up to 20 points.
- Maintenance M: up to 25 points.
- Site quality Q: up to 15 points.
- Social activity S: up to 10 points.
- Listing completeness C: up to 15 points.
- Community support V: up to 15 points (12 from votes, 3 from discussion).
Uptime rewards a product that actually works
Uptime is based on daily observations from the latest thirty-day window. Seventy percent of the component comes from the share of successful checks. The remaining thirty percent comes from the median response time of successful checks, not the single fastest response.
A response at or below 800 milliseconds receives a 30-point speed bonus; at or below two seconds it receives 22; at or below five seconds it receives 12; a slower successful response receives 4. A parked domain receives zero regardless of its HTTP status.
U = min(100, 70 × available_days / observed_days + speed_bonus)speed_bonus = 30 when median ≤ 800 ms; 22 when ≤ 2,000 ms; 12 when ≤ 5,000 ms; otherwise 4.Maintenance uses the freshest verified date
A product should not need to rewrite its homepage every week to look alive. NeedSift takes the newest trustworthy date from five independent paths: a meaningful homepage change, the product’s own changelog or blog, an App Store or Google Play release, a newly published sitemap URL, or a public GitHub or Telegram update.
The first scan creates a baseline and does not pretend that everything already present is a new update. A product also receives a seven-day launch window from its NeedSift creation date. After that, it must demonstrate activity. Store, sitemap, and social sub-scores remain visible for explanation, but their freshest verified dates flow into maintenance so the total does not reward the same release several times.
M(age) = 100 ≤7d · 85 ≤30d · 60 ≤90d · 35 ≤180d · 10 otherwiseage is measured from the newest verified activity date or, when no activity has been observed yet, the product’s creation date.Site quality measures trust, not website size
The quality analyzer can give a focused one-page indie product the same 100 as a large website. It looks for useful metadata, mobile support, a favicon and canonical or language signal; legal and contact routes; pricing, documentation, download, or sign-up paths; a changelog; enough real product copy; and evidence that the page actually describes the listed product.
Metadata contributes up to 40 raw quality points, trust and product structure 36, identity 12, and substance 12. A page with fewer than forty words has its result halved. A parked or for-sale domain receives zero. NeedSift checks at most eight homepage images: when at least three are sampled, broken images subtract 10, 20, or 30 points depending on their share. This is why a visually broken product page cannot receive full quality credit merely because its meta tags are correct.
Q = clamp₀₋₁₀₀(metadata + trust + identity + substance − image_penalty)The final ranking receives 15% of this normalized quality result. Volume of pages and marketing traffic are not inputs.Public activity and profile completeness
For public activity, each reachable GitHub or Telegram profile adds 15 raw points, capped at 45. A newly observed post or commit sets the social score to 100. Otherwise, activity within seven, thirty, or ninety days adds 55, 40, or 20 points. X links are not crawled without a reliable public interface. If a product lists no trackable public profile, social is neutral at 30 instead of becoming a penalty.
Completeness is intentionally finite. A logo contributes 3 points. Screenshots contribute 1.5 each up to 4. A description contributes 2 points from 120 characters and 4 from 300. A tagline adds 1; useful link coverage adds up to 2; a category adds 1. Adding ten duplicate links or hundreds of screenshots cannot increase the result.
S = min(100, 15 × reachable_profiles + freshness_bonus); S = 30 when untrackedfreshness_bonus = 55 for ≤7 days, 40 for ≤30 days, 20 for ≤90 days; newly observed activity makes S = 100.C = logo(3) + screenshots(max 4) + description(max 4) + tagline(1) + links(max 2) + category(1)Completeness is capped naturally at 15 points and rewards useful evidence rather than profile volume.Votes and discussion help, but cannot purchase the catalog
NeedSift has positive votes rather than a positive-and-negative rating scale. A Wilson interval is therefore the wrong model, while an IMDb-style Bayesian average would require a meaningful rating value to shrink toward a catalog prior. Instead, NeedSift uses a logarithmic curve: early genuine support matters, returns diminish quickly, and community influence stops at fifteen points.
The top of the curve is not a fixed number of votes. Full vote points sit at the 90th percentile of weighted votes across all approved products, with a floor of ten. In plain words, a product earns the full twelve vote points when it is better supported than nine in ten products in the catalog. A percentile is used instead of the maximum because one brigaded listing can move the maximum, but it cannot move the 90th percentile. The floor stops a young catalog from handing out full points for a single vote. The scale is recalculated on every daily scan.
Voting requires authentication and one account can hold only one vote per product. If the account was less than twenty-four hours old when the vote was cast, that vote receives a weight of 0.25. An established account receives 1. This does not solve every coordinated campaign, but it makes disposable launch-day accounts four times less effective and creates a clear foundation for anomaly review.
W = Σ vote_weight; vote_weight = 0.25 if account_age < 24h, otherwise 1Account age is measured at the moment of voting, so waiting later does not retroactively upgrade a suspiciously fresh vote.V_votes = 12 × min(1, ln(1 + W) / ln(1 + W₉₀)); W₉₀ = max(10, P90 of W across the catalog)At the minimum scale one full vote is about 3.47 points, three are about 6.94, and ten reach the 12-point ceiling. As the catalog grows, W₉₀ grows with it and the same number of votes is worth proportionally less.V = V_votes + V_discussionDiscussion is described in the next section and adds at most 3 points, so V never exceeds 15.Discussion counts a little
Products that people actually talk about are usually products people actually use. Since version 2, the community component also counts discussion under a product. The unit is a person, not a message: each distinct commenter counts once, however many comments they write, so a long argument between two accounts does not look like a crowd.
Only comments that passed moderation count. Comments by the product’s own maker do not count, because a builder answering questions is welcome but must not raise their own score. Commenters whose account was less than twenty-four hours old at their first comment count as 0.25, the same discount as fresh-account votes. Hidden, rejected and deleted comments count as zero.
The weight is deliberately small. Accounts are cheap and comment text is easy to generate, so discussion is a tie-breaker between otherwise similar products, not a lever. It follows the same catalog-relative scale as votes, with a floor of five commenters.
D = Σ commenter_weight; commenter_weight = 0.25 if account_age < 24h at first comment, otherwise 1One entry per distinct commenter with at least one approved comment, excluding the maker.V_discussion = 3 × min(1, ln(1 + D) / ln(1 + D₉₀)); D₉₀ = max(5, P90 of D across the catalog)At the minimum scale one established commenter is worth about 1.16 points, three about 2.32, and five reach the 3-point ceiling.A worked example
Consider a product with perfect uptime, activity in the last thirty days, a site-quality result of 80, a social score of 70, thirteen completeness points, three established votes and no discussion yet, in a catalog that is still at the minimum community scale. The product earns 20 uptime points, 21.25 maintenance points, 12 quality points, 7 social points, 13 completeness points, and 6.94 community points.
Its final score is 80.19. More votes and discussion can still help, but even enough of both to hit the caps would add only 8.06 more points. The stronger path is to improve the product evidence itself: repair broken media, keep the site available, publish a real release, complete the listing, or add a useful changelog.
20 + 21.25 + 12 + 7 + 13 + 6.94 = 80.19Example inputs: U=100, M=85, Q=80, S=70, C=13, W=3, D=0, W₉₀=10.Why this differs from launch feeds
Time-decay feeds such as Hacker News are built to surface fresh stories quickly: popularity loses power as the submission ages. NeedSift has a different job. A useful product should not disappear merely because it launched months ago, but it should gradually lose maintenance credit if every public sign becomes stale. The stepped maintenance window gives new products a fair start and lets older products recover immediately by shipping verifiable work.
Research on open-source abandonment also shows why a single last-commit date is not enough to describe project survival. NeedSift does not claim that any one public trace proves product health. It combines independent paths and deliberately caps every component. The formula will evolve, but changes should remain explainable and testable.
The score is inspectable, not a black box
Every component is stored by the backend and exposed on the product page in the “Why this score” block. Builders can see uptime, maintenance, site quality, social activity, completeness, and community contribution instead of guessing why a competitor moved above them. Catalog order changes only after the backend recalculates scores; it does not reshuffle in the browser while somebody is reading.
Transparency does not mean publishing every anti-abuse threshold forever. It means publishing the normal rules, separating measured facts from editorial decisions, and explaining material changes. The goal is not a mathematically perfect definition of quality. It is a ranking whose incentives point toward reliable products, honest maintenance, and useful public work.
Version history
The formula changes as NeedSift learns what separates maintained products from abandoned ones. Each version below lists what changed and why. Scores are recalculated by the next daily scan after a change ships.
- v2 — September 25, 2026. Community support now combines votes (up to 12 points) and discussion (up to 3 points): distinct commenters with approved comments, excluding the maker, with fresh accounts discounted. Full community points are no longer a fixed number of votes: they sit at the 90th percentile of the catalog, with floors of 10 votes and 5 commenters, so the scale grows together with NeedSift.
- v1 — September 24, 2026. First public formula: uptime 20, maintenance 25, site quality 15, social activity 10, completeness 15, and votes 15 on a fixed logarithmic curve, V = min(15, 5 × ln(1 + W)), with fresh-account votes weighted 0.25.